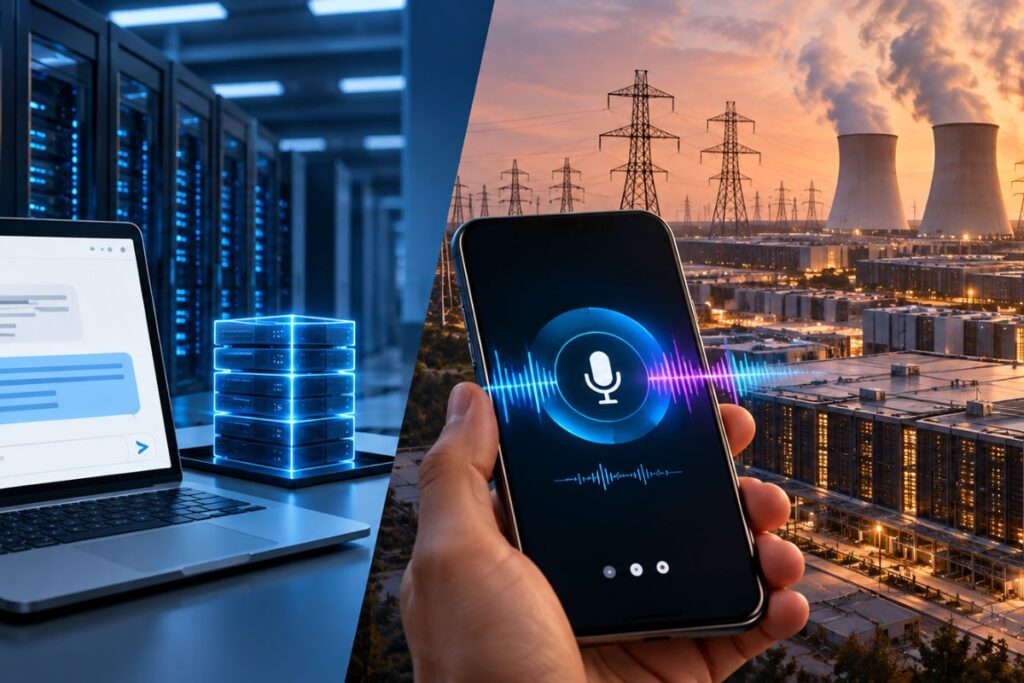
Opting for a five-minute voice conversation with Google’s Gemini 3.8 rather than a text exchange burns through 18 to 24 times more electrical power and cooling water. This massive environmental toll boils down to two hard engineering constraints: rendering lifelike synthetic speech requires processing thousands of additional data tokens per second, while the demand for instant, lag-free responses completely shatters the energy-saving batch processing routines that modern data centers rely on.
Why does generating realistic synthetic speech require so many tokens?
Synthesizing human speech demands up to 60 times more data tokens than generating text because acoustic codecs must process multiple layered sound streams every second. While a 150-word text answer requires roughly 200 text tokens, 60 seconds of conversational audio demands thousands of discrete tokens to render natural pitch, inflection, and cadence.
This explosion in volume is driven by residual vector quantization (RVQ). Residual vector quantization is an audio compression method that stacks multiple parallel codebooks to capture fine acoustic details such as breath and pacing. Modern neural audio codecs like SoundStream sample at 50 frames per second across these stacked codebooks, generating hundreds of discrete audio tokens every second compared to the handful needed for text.
Every second of synthesized voice requires processing dozens of these stacked frames simultaneously. The total computational payload scales linearly with that token count.
| Interaction Type | Token Volume (approx.) | Server Processing | Relative Energy Cost |
|---|---|---|---|
| 150-Word Text Query | 200 tokens | High-efficiency batched queues | 1x (Baseline) |
| 60-Second Voice Chat | 12,000+ tokens | Isolated low-latency processing | 18x to 24x |
How does conversational latency increase server power consumption?
Maintaining a sub-300-millisecond response window to mimic natural dialogue forces data centers to run processors at minimal batch sizes, multiplying energy consumption per token by 3.5x to 5x. Because servers cannot queue voice requests into high-efficiency batches without introducing noticeable conversational lag, the hardware must operate near peak wattage for individual users.
Batching is a standard data center efficiency method where hundreds of user queries are grouped and processed simultaneously in a single computational pass. Text models rely heavily on this technique to keep electrical draw low per user. Real-time voice completely removes this efficiency advantage.
According to benchmark data on Google Cloud TPU v5p architectures published by EaseCloud, pushing hardware to serve individual streaming sessions rather than batched text queues causes energy draw per token to spike sharply. The physics of conversational latency compounds the issue: an underlying 20-fold token increase multiplied by a four-fold latency tax establishes the true baseline compute cost.
Does commercial API pricing cover the real hardware costs of voice AI?
Current cloud rate cards indicate that technology providers are heavily subsidizing conversational voice outputs compared to text. While Google Cloud charges developers pennies per thousand audio tokens, operating the underlying custom silicon costs dozens of dollars per chip hour in raw electricity and hardware depreciation.
According to Google Gemini API pricing schedules tracked by OpsLyft, standard text output for Gemini 3.1 Pro costs $12 per million tokens, while budget tiers such as Flash-Lite cost $1.50 per million.
Running the physical hardware tells a different financial story. A standard eight-chip pod of Google’s flagship TPU v5p processors costs $33.60 per hour on-demand, according to EaseCloud, consuming constant electricity while generating those tokens. A Tensor Processing Unit (TPU) is Google’s custom-built silicon accelerator designed specifically for neural network machine learning workloads.
Google offsets this hardware reality through proprietary chip design. The company engineers TPUs to maximize performance per watt, and historical deployment data shows Google typically improves model inference efficiency by 2x to 4x within 18 months of launch through software distillation and kernel optimization.
How does voice AI impact Google’s 2030 climate goals?
Scaling voice AI directly strains municipal water tables and regional power grids, challenging corporate pledges to reach net-zero carbon emissions by 2030. Evaporative cooling for data centers requires millions of gallons of water annually to offset the high thermal output of real-time audio chips.
Google tracks this environmental impact through corporate disclosures, monitoring Scope 2 market-based emissions and Water Usage Effectiveness across its global operations. Generating significantly more compute per query increases the cooling load on facilities that rely on local municipal supplies.
These resource demands have already led to friction. Water consumption by Google data centers has led to contentious municipal water negotiations in The Dalles, Oregon, where local utility agreements face intense public scrutiny over watershed depletion.
What happens to regional electrical grids if voice replaces 10 percent of search?
If users switch one in ten daily Google searches to three-minute voice sessions, data center power demand will surge by an estimated 14 to 18 terawatt-hours (TWh) each year. That added demand exceeds the entire annual electrical consumption of the city of San Francisco.
According to search traffic metrics published by Omnibound, Google processes between 8.5 and 14 billion queries globally each day. Shifting even a small portion of that volume to voice creates an infrastructure bottleneck.
Connecting that volume of power to regional grids involves delays that software cannot fix. Grid operators like PJM Interconnection have overhauled large-load interconnection rules specifically to manage multi-gigawatt requests from AI data centers, warning that regional transmission lines cannot expand at the pace of current data center construction.
Evaporative water loss scales directly with this electrical surge. Sustaining a 14-terawatt-hour load on liquid-cooled hardware requires billions of gallons of continuous water evaporation each year to keep processing chips within safe operating temperatures.
Further reading on enterprise compute: See our analysis of why Indian data centre cooling capex faces asset stranding by FY28 and how AI data center subsidies drive commercial real estate arbitrage.
Related In-Depth Coverage
Clarity Times Science & Tech Bureau
The Clarity Times Science & Tech Bureau investigates artificial intelligence governance, semiconductor supply chains, biotechnology, and public health systems.