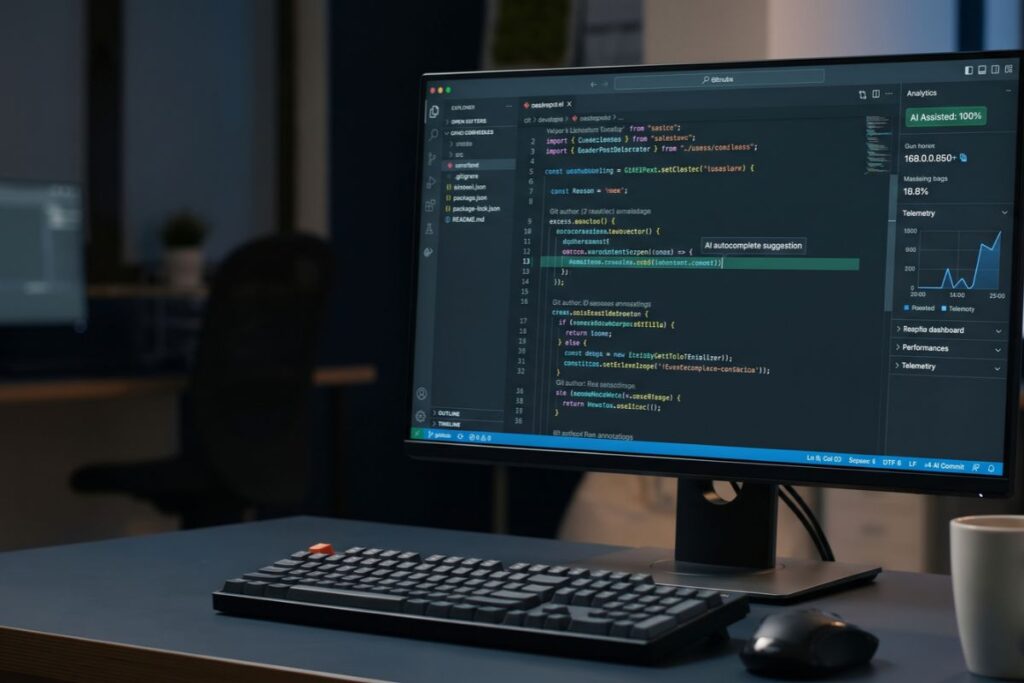
When tech companies report that 25% of their commits come from artificial intelligence, they rarely mean AI wrote a quarter of the actual lines of code. To understand how companies measure AI code, look at internal tracking dashboards: they routinely flag an entire human-written file as “AI-assisted” after a developer accepts a single two-line autocomplete suggestion.
How Does One Autocomplete Line Flag an Entire Pull Request?
Enterprise telemetry tools tag entire pull requests as AI-assisted by matching repository submissions against broad editor session activity rather than counting individual machine-written lines. Inside most large software organizations, measuring AI usage does not happen inside the code repository itself.
Git, the open-source version-control system engineers use to save and merge software changes, records which human user account submitted a change, not whether a keyboard or an artificial intelligence tool generated the characters.
To bridge that gap, internal developer-experience teams build reporting pipelines that join two disconnected data streams: coding-editor telemetry and repository commit logs. According to GitHub’s Lines of Code metrics documentation, GitHub Copilot Enterprise tracks activity through daily user- and team-level metrics, such as suggested lines versus accepted lines, rather than embedding line-by-line authorship markers directly inside a saved file. Even when a developer deletes an accepted suggestion moments later, Hivel’s expanded Copilot metrics guide notes that the acceptance event remains logged in the daily telemetry payload.
When an engineer writes a 200-line file from scratch, accepts a single two-line suggestion from an autocomplete tool, and submits a pull request, a formal request to merge new code into a shared project, commercial analytics tools often classify that entire submission as AI-assisted. According to Swarmia’s AI tool detection guide, pull requests can be tagged as AI-assisted not only via explicit commit trailers, but also through time-based matching whenever any commit is made by a developer who used an AI tool within the previous 24 hours.
Swarmia’s documentation confirms that if a developer simultaneously works on two separate tasks and uses an AI assistant on only one, 24-hour time-window matching still associates AI usage with both pull requests.
Why Does Line-Level AI Code Attribution Break When Humans and AI Co-Edit?
Line-level AI code attribution fails because developers routinely rename variables, delete extra lines, and rewrite AI-suggested functions before saving a file. Once a human edits a suggested block of code, automated tracking tools lose the ability to separate machine output from human labor.
To work around this limit, software engineering intelligence platforms, specialized analytics tools such as Jellyfish, LinearB, Swarmia, and DX that aggregate Git and workflow data, rely on proxy heuristics rather than character-level authorship proofs. Because each vendor uses a different matching rule, two companies with identical coding habits can report completely different AI commit metrics:
- Commit-level and trailer flags: Any pull request containing a co-author trailer (such as Made-with: Cursor) or an agent label counts toward the AI-assisted total, regardless of how many lines the human rewrote afterward.
- 24-hour session-window matching: Because some AI tool providers expose usage data only in daily aggregates, platforms like Swarmia offer a default matching mode that flags any commit pushed within 24 hours of an active AI session.
- Volume-based footprint ratios: According to Jellyfish’s AI output tracking guide, AI-assisted pull requests consistently run larger in total lines added than human-only requests, meaning any footprint metric calculated by raw volume overstates AI’s actual contribution.
Engineering leaders and analytics vendors point out that tracking every keystroke inside an editor creates major operational trade-offs. Recording granular keystroke-level telemetry raises developer privacy concerns, adds client-side performance overhead, and still cannot resolve hybrid authorship when a developer manually refactors an AI-suggested block.
What Do Executives Announce vs. What Do Internal Dashboards Count?
Executives cite headline AI commit percentages on earnings calls without a shared industry accounting standard, while internal dashboards rely on unstandardized vendor definitions. During Alphabet’s Q3 2024 earnings call, Alphabet CEO Sundar Pichai stated that more than a quarter of all new code at Google is generated by AI and then reviewed and accepted by engineers, a benchmark Microsoft leadership has echoed with similar 20% to 30% figures.
Those announcements carry no standardized accounting rules. Unlike revenue or capital expenditures governed by federal reporting standards, “AI-generated code” has no shared industry definition, and companies do not report or audit these percentages in formal U.S. Securities and Exchange Commission Form 10-K or Form 10-Q filings.
| Metric Type | What It Actually Measures | Where Distortion Enters |
| Editor Acceptance Rate (e.g., 75% claims) | Share of inline suggestions accepted via Tab/Enter inside the IDE | Includes boilerplate, single-line completions, and code deleted before commit |
| AI-Assisted PRs / Commits (e.g., 25% claims) | Merged commits or pull requests linked to an active AI session or tag | A few AI-assisted lines can tag an entire multi-hundred-line human pull request |
| Line-Level Survival (Rarely published) | Share of AI-authored lines remaining in production after 14 to 30 days | Requires tracking post-merge rewrites and short-term code churn |
How Do Executive Targets Distort AI Commit Metrics?
When leadership ties quarterly engineering goals to AI adoption percentages, dashboard teams face pressure to use inclusive counting rules that inflate top-line adoption rates. According to Datadog’s analysis of DevEx measurement pitfalls and explainx.ai’s research on AI specification gaming, Goodhart’s Law- the principle that when a measure becomes a target, it ceases to be a good measure- rapidly distorts engineering dashboards once executives link objectives to AI usage.
When leaders set targets requiring teams to hit a specific AI commit threshold to justify enterprise license spending, broad counting rules deliver faster headline progress. Counting routine automated tasks, such as AI-generated unit tests, repetitive configuration templates, and single-line tab completions, raises the top-line adoption rate without changing how core architecture is written.
According to Faros AI’s analysis of lines-of-code vanity metrics, measuring raw AI code volume rewards verbose output rather than working software.
What Does True AI Code Survival Rate Tracking Require?
Measuring a true AI code survival rate requires parsing source code into an abstract syntax tree, a structured map of functions, variables, and logic blocks, and tracking whether those blocks survive post-merge refactoring over weeks. Codegen’s AST technical reference notes that abstract syntax trees allow static-analysis systems to trace structural logic rather than raw text lines across saved file versions.
Longitudinal repository studies show why survival tracking changes the picture. According to GitClear’s 2026 Maintainability Gap research, which analyzed 623 million changed lines from 2023 through 2026, duplicated code blocks rose 81%, from 40.3 to 73.0 per million changed lines, while refactoring activity fell from 21% of changed lines in 2022 to 3.8% in 2026. Similarly, Calidad Infotech’s code-quality framework highlights short-term churn, the share of newly merged lines rewritten or reverted within 14 to 21 days, as a necessary counterweight to raw commit volume.
Until enterprises pair adoption dashboards with post-merge survival and churn audits, headline figures like “25% AI commits” will continue to measure how frequently developers touch AI tools, not how much durable production software machines actually write.
Frequently Asked Questions
How do tech companies measure 25% AI commits?
Tech companies typically join coding-editor telemetry logs, such as GitHub Copilot Enterprise daily usage payloads, with Git repository commit records. Analytics platforms like Swarmia and Jellyfish then tag pull requests as AI-assisted using co-author trailers or 24-hour active session windows rather than counting surviving AI-written lines.
Why is “75% AI code” different from “25% AI commits”?
“75% AI code” usually measures the raw acceptance rate of inline autocomplete suggestions inside a developer’s editor, including boilerplate and lines deleted before saving. “25% AI commits” measures merged pull requests or commits linked to an active AI session, though a single accepted two-line suggestion can still tag an entire 200-line human file.
Can Git track which exact lines of code were written by AI?
No. Git records which human user account submitted a commit, not whether a keyboard or an AI assistant typed the characters, and once a human renames variables or edits a suggestion, line-level authorship tracking breaks down.
How much AI-generated code actually survives in production?
While tech companies rarely publish line-level survival rates, GitClear’s 2026 analysis of 623 million changed lines found that duplicated code blocks increased 81%, from 40.3 to 73.0 per million changed lines, while refactoring dropped from 21% in 2022 to 3.8% in 2026.
Praseetha K
Praseetha K is the Managing Editor of Clarity Times. She edits, verifies and publishes the newsroom's articles, and also writes analysis on policy, law, business and technology. Articles she writes are edited by the Editor-in-Chief before publication.